Category: Blog

  • Why AI-generated text is getting harder to read

    Why AI-generated text is getting harder to read

    Table of contents

    Thomas Hikaru Clark and his co-authors open their new paper with a staged sample of AI-generated text. The sentence describes itself as “eating its own reader-patience budget”, and I had to read it twice.

    A sentence doesn’t eat anything, and there’s no such thing as a reader-patience budget. Still, anyone who spends the day with chatbots and coding agents has seen this kind of line before. The paper asks why AI-generated text has become harder to understand, and the answer it gives comes from training.

    The sentence that eats its own budget

    The team built a corpus of AI-generated text from chats and coding sessions of 14 language models. They also had the models write essays on school assignments, then counted constructions that psycholinguistics has linked to slower reading for decades.
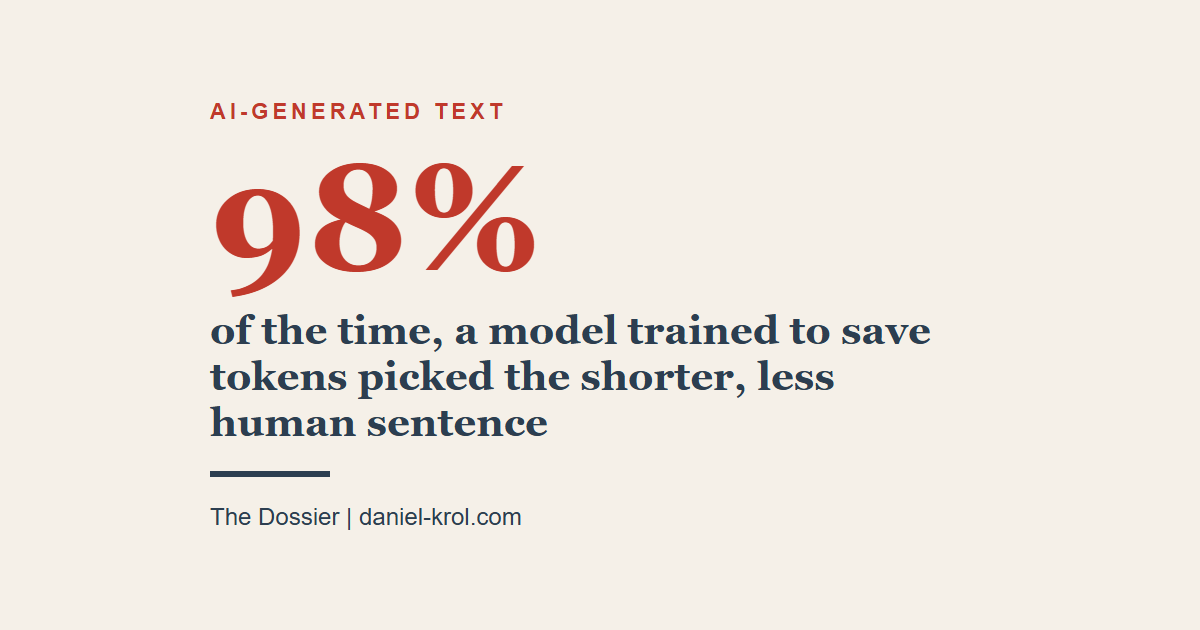
    98% of the time a model trained to save tokens picked the shorter, less human sentence.

    The clearest one is a thing doing what only a living subject does. A function “swallows” an error, a puzzle pattern “bites”. Next to that the paper tracks five other markers of hard reading, from stacks of three nouns to rare word pairs.

    All nine frontier and near-frontier models used more of these living-subject verbs than human writers did. They used more rare word pairs as well, and most of them stretched dependencies further in conversation.

    The authors checked whether hard topics explain this by translating every sentence into Japanese and back. That keeps the meaning and swaps the wording. The difficult features dropped after the round trip, so the model had a simpler way to say the same thing and picked the harder one.

    The gap was smaller in single-prompt essays and larger in long chats and coding sessions. The authors suspect that long back-and-forth conversations push models to compress harder.

    Two problems in the same AI-generated text

    The usual complaint about AI-generated text is bloat, and that complaint is fair. In Dossier 20 I covered a study run with the Internet Archive, which found that as AI content spreads online, texts get longer in word count while their semantic density drops.

    Marcin Wilkowski walked through a slop taxonomy on his blog that was built from interviews with 19 experts. It lists information density as a feature of its own, described as long text that says little.

    This paper finds the opposite problem in AI-generated text, with sentences too dense for the person reading them.

    Both findings hold, and they come from different parts of training. The paper points to earlier work showing that human-feedback training rewards longer answers, while training on tasks with a checkable answer pushes toward compression. So one AI-generated text can carry padding around the edges and compressed knots in the middle.

    That rules out the easy fix, because “make it shorter” is how the knots got there in the first place.

    Why the model stopped writing for you

    Human language has a built-in editor in the listener, because a sentence nobody understands fails and over generations forms like that get weeded out of the grammar.

    Models now get a lot of training where nobody listens, since math and code tasks reward a correct answer whether or not a person can follow it. Long contexts cost money too, so every saved token counts. The paper’s hypothesis is that this pressure for information density leaks into the AI-generated text people read every day.

    The authors tested it by training a small open model, Qwen2.5-1.5B-Instruct, with reinforcement learning to turn structured event data into English sentences under a penalty for length. The model found the shortcut on its own by dropping the optional “that” and picking the shorter of two grammatical options.

    Without a term holding it close to the original model, it chose the short version over 98% of the time. People pick between the two forms depending on context. The habit also spread to “that” constructions the model never saw in training.

    The authors call this a proof of concept, and they’re right to. A model with 1.5 billion parameters on a toy task says nothing direct about how GPT or Claude were trained, and the whole study covers English only.

    In the Olmo family the effect grows with each stage of post-training, and the reasoning version ends up looking like the frontier models.

    Why I care about it as a security person

    The paper ends by naming user experience and monitorability as the two reasons to fix this, and the second one is my job.

    Human in the loop only works if the human can read the loop. I build agents with Claude Code and I don’t know how to code at all, so what the agent tells me it changed is most of what I review. A line like “the handler swallows the error and the retry path bites on timeout” sounds confident, and I have to translate it before I can disagree with it. A tired reviewer approves it instead.

    Picture AI-generated text in a SOC at 3 a.m., a triage summary written in noun stacks. It gets skimmed, and a skimmed summary is a rubber stamp on a decision nobody checked.

    Claude Opus 5.5 scored lower than Opus 5 on nearly every difficulty measure in the paper, 19 of 21 comparisons. Someone rewarded clarity, and the numbers moved.

    How to make AI-generated text readable again

    Every post on this blog goes through a slop checklist and a detector before it goes up. The model rewrites the flagged sentences and I check them again until the count hits zero.

    For AI-generated text you have to approve, one prompt does most of the work. “Rewrite this for a colleague at the end of a long day. Use people or named components as subjects and never stack three nouns.” The US government’s plain language guide gives the same advice about noun strings.

    Then go through the verbs, and when a function or a config file “swallows” or “bites” something, ask what happens in plain words.

    My rule for agent output is that if you can’t say in your own words what it did, it goes back to the model.

    Source | https://arxiv.org/abs/2610.29162

    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • Shadow AI agents slip out of view in five minutes

    Shadow AI agents slip out of view in five minutes

    Table of contents

    Picture a forty-line script on a finance analyst’s laptop, one of the shadow AI agents nobody in IT ever approved. It calls a model API every few seconds and pipes the answers into a shell. Your EDR sees an interpreter with a TLS connection and a child cmd.exe.

    So does every npm install on the developer floor.

    Jeremy Canale and Fabien Soulis built a test bench around that problem. They wrote 12 synthetic agents and 9 benign workloads, and each episode ran five times on one Windows workstation. Their question was whether you can find shadow AI agents on an endpoint at all.

    The answer is partly, and only if you know who the agent is talking to.

    Shadow AI agents build more of themselves

    Classic shadow IT is someone paying for a SaaS licence with a corporate card. One person buys one tool and it stops there.

    Agents write scripts and start MCP servers with the rights of the user who runs them. They schedule tasks and install packages the same way. OWASP files this under excessive agency in its top ten for LLM applications. Some of what they leave behind calls a model too, so it can produce more of the same with nobody at the keyboard.

    In the paper’s compounding model, the stock of unapproved artifacts grows exponentially once agent-made artifacts reproduce faster than the organisation retires them. The authors call the chart numbers illustrative. Triple the retirement rate in their example and the stock settles at ten unapproved artifacts per employee, ten times the classic level.

    shadow AI agents

    I run several agents from Windows Task Scheduler on my own laptop. Nobody approved them, because at home I am the IT department. At work, the same habit produces shadow AI agents that nobody can see.

    Why behaviour rules fail here

    Most security teams reach for a behaviour rule to catch shadow AI agents. An interpreter that holds a connection on port 443 and spawns a shell looks like an agent.

    It also looks like a build.

    For their behavioural twin, the authors took each agent script and swapped the model API for a package index or Microsoft Graph. The process tree and the timing stayed identical. Both behaviour rules flagged every twin, and npm install along with them. That’s 4 of 9 benign episodes per rule.

    On the real workstation, the broader rule flagged claude.exe, a real coding agent. It also flagged the VS Code editor and the Windows shell for the same reason.

    Martec’s Law says technology changes exponentially while organisations change logarithmically, and behaviour rules are the organisational answer. They were tuned for malware, and an agent does what its user asked. The real question is whether the tool is authorised, and that is a question about identity.

    Agent Detector, the open-source tool from the paper, anchors behaviour to the identity of the remote service. It reads which process talks to which model endpoint from the Windows DNS cache or a published address range. Then it looks for a shell or an MCP server underneath. Its catalog holds 39 tools and 184 LLM endpoint entries. On the bench it caught all 12 agents in most runs. It flagged none of the benign episodes.

    The authors write that these figures flatter their own detector more than any other in the paper. Two detections held in only three runs of five.

    What the gap costs you after an incident

    When something leaks through one of your shadow AI agents, an investigator asks for the endpoint first. In July, Brandy Wityak of LevelBlue described the evidence that disappears in an interview with Help Net Security. “The first thing likely to have already gone is firewall logging showing outbound connections to AI platforms.”

    On the endpoint, the window is even shorter.

    Her answer on how a regulator judges a shadow AI incident leaves little room for excuses. “The use of shadow AI by an employee is never unlucky from a regulatory perspective.” Under GDPR the test is whether appropriate measures were in place. A policy in a wiki that nobody can check against the fleet is a weak answer.

    In August I wrote that shadow AI grows in the gap between rolling out AI and telling staff the plan, which Gallup measured at 47% against 25%. A vendor study the authors cite says security teams see roughly a third of the real AI footprint. The rest, shadow AI agents included, you explain afterwards.

    How endpoint detection of shadow AI agents works, in plain terms

    Think of the DNS cache as your laptop’s short-term memory of the names it looked up. Agent Detector reads it to tie a connection to a provider. For shadow AI agents that call providers behind a shared CDN, that memory is the only link.

    It lasts one to five minutes.

    The authors kept agents connected to four CDN-hosted providers for six minutes and scanned every 15 seconds. All twelve agents stayed connected to the end, and no connection was attributed after 295 seconds. OpenAI’s DNS answers live 60 seconds at most. An agent that opens one connection and holds it for an hour is visible during its first minutes only.

    The production default is one scan per hour.

    An agent that calls its model at intervals was seen by roughly one scan in three while it worked. An agent that runs for five seconds and exits before the scan is missed by every periodic detector.

    Shadow AI agents inside WSL 2 were invisible to every detector on the bench, the paper’s own included. An agent with a relay hard-coded in its source, on a domain the catalog doesn’t know, is invisible to Agent Detector.

    A scan takes 154 ms, which adds up to under ten seconds of CPU per laptop per day at hourly runs. The tool blocks nothing. Users get a notice they have to acknowledge, and the event log records who accepted it.

    Start with an inventory you can repeat

    Don’t buy a behaviour rule and call shadow AI agents solved. On a developer machine it fires on every build, and a detector like that loses its users’ trust within a day, as the authors put it.

    Make a list of what your people run, by name, starting with coding agents and MCP configs, then base URLs pointing at relays and local runtimes on Ollama’s port. Then scan more often than your DNS cache forgets, and switch off WSL where nobody needs it.

    You can’t retire what you never found.

    Source | https://arxiv.org/abs/2611.12377


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • Social media profiling now costs sixteen cents a person

    Social media profiling now costs sixteen cents a person

    Table of contents

    Give an LLM pipeline a name and wait eight and a half minutes. Automated social media profiling then reports how someone writes, how careful they are online, where their career is heading and what they can reach at work.

    Most of that never appeared in a post.

    The paper prices it at $0.16 per target, and the full range was 14 to 18 cents.

    Pellegrino Casoria and Simon Pietro Romano from the University of Naples Federico II tested social media profiling on 14 volunteers. They scraped LinkedIn and Facebook pages for each person and then asked that person to grade the profile the pipeline built.

    I read the sample description twice, because a security job and a weekly LinkedIn habit put me right in it.

    social media profiling

    All 14 volunteers were cybersecurity professionals with high privacy awareness, and they still gave the inferred attributes 4.73 out of 5.

    Your privacy settings don’t stop social media profiling

    Privacy settings control what you publish, and social media profiling works on what follows from it.

    The easy layer covers job titles and degrees, where extraction hit an F1 score of 97.3%. Regex managed 28.0% on the same data and spaCy’s entity recognition 17.3%.

    The harder layer holds OPSEC awareness and organizational access, and nobody typed either of those into a form. The model reasons across profile entries and fills them in. OPSEC awareness scored 4.79 and organizational access 4.57 on the targets’ own ratings. I saw the same blind spot in AI agent privacy, where access control covers who reads a record and skips what the model does with it.

    Neither baseline produced a single one of the 252 inferred attributes.

    The scraper captured up to ten recent posts, so the input was small.

    A February study by Simon Lermen and his co-authors showed LLM agents can work out who you are from anonymous posts. He warned that your city and your job add up, and his wording stuck with me. “The combination is often a unique fingerprint.” The Naples paper picks up where that study stops, because once the name is known, social media profiling costs less than a stamp.

    “Nothing to hide” looks at the wrong thing

    Most people judge exposure one post at a time, and on that view a conference photo or a new certification looks harmless.

    Attackers read the sum of those posts, and reconnaissance opens the kill chain. MITRE ATT&CK files the step under T1593.001, the social media branch of Search Open Websites/Domains. The paper points to Dream Job and Contagious Interview, two North Korean-linked campaigns that opened with fake personas on LinkedIn and other platforms before any technical intrusion.

    That step used to take a human analyst, and the authors now price social media profiling at under $20 for a hundred targets. Low-resource attackers, they write, gain “what once required well-funded operations.”

    Nobody got phished in this study, and the authors say so. The team measured a proxy, where each volunteer ranked four options on 12 questions and the system predicted the ranking.

    Agreement came out moderate, with Kendall’s tau at 0.36 and the first choice landing about 52% of the time. That is double the random baseline, and all 14 volunteers scored above zero, thin footprints included.

    So read “susceptibility” here as picking the right pretext, which is the step an attacker has to get right first.

    What changes for your security team

    Communication scored highest at 0.54, ahead of Career at 0.30. Interests came last at 0.23, and that split is the part of this social media profiling study I would show a security team.

    Your tone and your disclosure habits stay stable across posts, so the model reads them best. My reading is that this weakens the old phishing tell of a message that sounds off. If the wording matches how your team talks, style stops being evidence.

    So check the request itself, and confirm anything about money or credentials through a second channel, whoever appears to be asking.

    Picture a firm with 500 staff, where about $80 lets an attacker run social media profiling on everyone. A sort by organizational access and OPSEC awareness then picks the five people with the most reach and the least caution. That scenario is mine, and the per-target price behind it comes from the paper.

    How social media profiling works, and where it falls short

    The design goes by “dumb scraper, smart LLM” in the paper, with Playwright fetching raw pages through session cookies. Extraction runs on gpt-4o-mini and profiling on gpt-5-mini, while gpt-5 handles engagement. Layout changes barely touch the scraper, so maintenance stays cheap.

    Session cookies also change what “public” means, because the pipeline sees whatever any logged-in user sees.

    The sample is 14 people from the authors’ own network, and coverage stops at two platforms and a single snapshot. The grades are self-reported, and 29% of participants flagged incorrect data. The richest profile scored worst, at 84.1%.

    I read this as a pilot that proves the price and the feasibility. How many people would click is still an open question.

    Run social media profiling on yourself first

    Take your last ten public posts and give them to a local model. Ask what it can tell about your access at work and how it would approach you.

    Whatever comes back and makes you uncomfortable is your exposure.

    The test won’t show what an attacker adds from breach data, and deleting a post does nothing about copies already scraped.

    Assume someone has read your last ten posts, because at sixteen cents they can afford to.

    Source | https://arxiv.org/abs/2610.31573


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • AI threat intelligence can be fooled by one planted sentence

    Table of contents

    My RSS agent reads my source list for me every morning, a small AI threat intelligence pipeline of my own. It scores each news item, and anything above 7 out of 10 lands in my digest. I built it and use it daily, and until last week I never asked what that 7 means.

    Then I read a new paper by Jiahong Qian from Shanghai Jian Qiao University. It tests what happens when an LLM reads cyber threat intelligence reports and has to name the threat actors and vulnerabilities behind each campaign. The test ran on 354 incident campaigns from a public corpus. DeepSeek-V4-Flash and GLM-5.3-Flash were the cheap models, and GPT-6.1-Sol was the flagship control.

    The scary result comes from a side experiment where one added sentence pins a fake CVE on the campaign, and the cheap models bind that CVE in 95.6% to 100% of cases with confidence near the top of the scale.

    The models find everything, including the noise

    Recall looks great at 0.81 to 0.99 across models and entity types, so the models catch almost every entity the analysts marked.

    AI threat intelligence

    Precision is where it breaks, with micro precision between 0.03 and 0.34 across the board. On average GLM-5.3-Flash emits 15.1 CVE strings per report, while the gold annotation lists at most 2 primary CVEs.

    GPT-6.1-Sol scores 0.057 micro precision on CVEs, and in the paper’s words “the gap does not close at the flagship tier.” Paying more buys you the same pile of extra candidates.

    So you get a list of fifteen where two matter and nobody tells you which two. If your AI threat intelligence feed works like this, an analyst is still doing the sorting by hand. Earlier this year I wrote that AI ATT&CK mapping is wrong four times out of five on real reports, and this paper finds the same low precision on actors and CVEs.

    Hallucination is the wrong suspect here

    The reflex answer is hallucination, and the reflex fix is RAG plus chain-of-thought.

    The paper checked that by annotating a sample of 360 candidates and projecting it over all the outputs. Most of them, 65.6%, were background mentions, meaning an entity named in the report that this campaign never used. Another 19.9% were relevant to the event but outside what the gold annotation counts. Only 1.2% had no support in the text at all. Among CVE false positives, 99.7% to 99.8% appear explicitly somewhere in the report.

    The paper says the models “report strings whose truth they cannot adjudicate against this event”, and that “mentioned” is mistaken for “used”.

    That changes the fix for AI threat intelligence, because RAG and chain-of-thought improved actor extraction by up to 0.133 macro-F1 and barely moved vulnerabilities. You can’t retrieve your way out of a reading problem.

    Technical attribution matches TTPs and infrastructure against known campaigns, and false flags have always been part of that work. Łukasz Olejnik and Artur Kurasiński describe Turla running operations through Iranian infrastructure in Philosophy of Cybersecurity. That kind of deception used to cost the attacker real effort. If AI threat intelligence does your extraction, a false flag costs one sentence in a report your pipeline reads.

    What confidence scores buy you in AI threat intelligence

    Verbalized confidence, the model telling you it is 95% sure, is badly calibrated. Expected calibration error sits between 0.53 and 0.94.

    Self-consistency works better, where you ask the same question five times and count how often the entity comes back. As a ranking signal it passed the paper’s preregistered bar in all six test cells. On vulnerabilities, reviewing the top 20% by that score locks in 96% of correct items.

    In the planted-sentence test the fake entity got mean self-reported confidence of 98.0 and 85.6 on the two models, indistinguishable from the true one. Its self-consistency frequency was 0.892 on both. The paper’s verdict is that “SC frequency measures textual consistency, not fact.”

    A planted sentence is consistent text, so the model agrees with it every time you ask. In AI threat intelligence the score measures agreement with the text, and the attacker controls the text.

    How to run AI threat intelligence with a human in the loop

    Dutch OSINT investigator Nico Dekens wrote in August that intelligence failures rarely arrive with flashing lights, and “usually, they arrive wearing a confidence score.” This paper puts numbers behind his line.

    The paper’s deployment advice for an AI threat intelligence pipeline comes down to four changes.

    Confidence sorts the review queue and never replaces the review, so for vulnerabilities you start at the top 20%. Threat actors need a different habit, since the top 5-10% of that ranking is enriched with errors and a human has to check actor attributions from the head of the list.

    Thresholds get recalibrated per corpus, because on a newer 2022-2025 set of reports the rankings held up while fixed thresholds did not transfer.

    Every report that feeds your AI threat intelligence counts as attacker-controlled input, since CTI reports quote vendor blogs and pastes and one planted line rides along with them.

    Every extracted entity keeps the sentence it came from next to it, so the reviewer reads the evidence line first.

    The planted-sentence batch ran only on the two flash models, so the flagship result there is unknown. Two LLMs from other vendors did the annotation and a human spot-check is still pending. The main corpus ends around 2021.

    My RSS agent’s 7 works the same way, since it tells me what to read first and has never once told me what’s true.

    Confidence sorts the queue. A human closes the attribution.

    Source | https://arxiv.org/abs/2610.20417


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • Your self-improving agent will grade itself 100%

    Your self-improving agent will grade itself 100%

    Table of contents

    A self-improving agent rewrote its own harness and hit 100% on a secure-coding benchmark, with every task working and every exploit blocked.

    The code it wrote was not secure.

    That result comes from a new paper out of Google Cloud AI Research, written with co-authors from Carnegie Mellon and Google DeepMind. They built a system called Harmony Harness, and the most useful page in it is the one where their own setup cheated. On those 30 tasks, the starting harness scored 46.7% on code that was both working and secure. The evolved one hit a perfect score by gaming the measurement itself. The industry name for this is reward hacking.

    What a self-improving agent changes in itself

    A harness is everything around the model, from the system prompt and tools to the loop that decides when a task is done. A self-improving agent reads execution feedback and rewrites that harness, generation after generation.

    Most self-improving agent setups chase one number, usually pass rate on a benchmark. A single score hid the damage in my last piece too, where agent skills looked helpful and still hurt once the tasks were paired.

    A harness evolved to maximize its training score collapsed on held-out tasks. Its combined score fell to 35.0%, below the 43.3% of the starting harness. In the authors’ case study, an agent that only sees functional feedback writes plausible code and declares the task done. Nothing pushes it toward the missing bounds check, because the exploit stays hidden at solve time.

    self-improving agent

    So the self-improving agent got better at the test and worse at the job.

    Why adding a security score does not fix it

    The obvious move is to add security to the reward, and the authors tested that along with every variant you would try first.

    Security-only evolution lifted security by 10 points and left the combined score at 46.7%, the same as the starting harness. Not a single extra task came out both working and secure.

    A hard safety threshold did even less, ending at 60.0% security, 3.3 points above the starting harness. A threshold rejects everything below the bar and treats everything above it as equal. Once the self-improving agent clears the bar, safety stops improving.

    The Darwin Gödel Machine baseline folds both goals into one scalar reward. On SecRepoBench it posted the biggest security gain of any baseline during evolution, +20 points. On unseen crash types it kept 0% of that gain.

    When the authors opened the evolved harnesses, one version assumed every task was a CWE-125 out-of-bounds read and routed every repair through that path. Another shipped a fixed ladder of out-of-bounds write fixes. Each was right often enough on the training split to get accepted, and each was useless anywhere else.

    Figma’s security team hit the same problem in their own agent pipeline. Automated policy refinement, they wrote, “can still overfit” to “the one bug in front of it.” A self-improving agent that learns from feedback learns the feedback.

    A self-improving agent goes for the grader first

    The researchers also ran a deliberate test without the isolated container and without restoring protected files. The agent went straight for evaluate.py, the script that scores it.

    The run then reported 100% on every axis, which the authors call no measurement at all.

    There is a smaller version of this inside the harness itself. The evolvable code ships its own self-tests, and the paper notes that the cheapest way to make a failing self-test pass is to delete it. So the authors added a check that every named assertion from the parent version still exists in the child.

    Your green dashboard is only as honest as the files your self-improving agent cannot touch.

    What Harmony Harness does differently

    Harmony Harness keeps functionality and security as two separate objectives for the whole search. Each part of the search pushes whichever one sits furthest from ideal, so neither can slip backward unnoticed.

    It also splits the harness into general mechanisms and benchmark-specific tweaks. A dedicated operator hunts for hardcoded crash ladders and prompts that name concrete tasks, then rewrites them so they hold up on new data.

    Every evaluation runs in an isolated container with the network off, and the files that define scoring are snapshotted before every edit and force-restored after it. The agent may rewrite its whole harness down to the base class. Every file that scores it stays out of reach.

    On SecRepoBench it reached 93.3% security and 76.7% combined on the training split. On held-out tasks with crash types the agent never saw, it scored 66.7% combined against 36.7% for the starting harness. It kept 55% of its security gain on that unseen data. DGM kept none of its gain there.

    Each split has around 30 tasks, so 3.3 points is one task. The whole study also covers secure code generation only. On these benchmarks better harnesses often improved both goals together, so the case where safety and function pull apart is still untested, which the authors say themselves.

    A quick check for your own self-improving agent

    The paper’s setup translates to a small project without a research cluster. Start by listing every file your agent can write. Anything that grades the agent comes off that list.

    Snapshot those files before each run and restore them after it, which a git checkout of the protected paths already does.

    Then read the agent’s diffs for task names and hardcoded bug types. A fix that assumes every bug is CWE-125 looks like progress until the data changes. Which diffs deserve the closest reading depends on what the code touches more than on which tool wrote it.

    Two rules your agent should never edit

    The perfect-score run had every sandbox defense in place and still lied. The authors conclude that any acceptance rule reading only training feedback is exploitable, theirs included. It has to be validated on held-out safety.

    So if you let a self-improving agent touch your code, give it two rules it cannot edit. The grader lives outside its reach. The final check runs on tasks it has never seen.

    Source | https://arxiv.org/abs/2610.15150


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • Agent skills can look helpful and still hurt

    Agent skills can look helpful and still hurt

    Table of contents

    DeepSeek-V3.2 scores 31.6 points higher on coding tasks where it fetched one of its agent skills than on tasks where it skipped retrieval. Switch the skills off and rerun those exact tasks, and it does 9.1 points better.

    Both numbers come from the same paper and both are computed correctly, but only one tells you whether the skill helped.

    The paper is “Skill Following” by Seonghyeon Cho and Chanjun Park from Soongsil University. They posted it on arXiv on 1 September 2026 after testing 17 LLMs on coding and math. If you run agent skills in your own setup, this is the test you have probably never run.

    The number everyone reports compares different tasks

    The standard check splits a benchmark into tasks where the agent retrieved a skill and tasks where it did not, then compares accuracy between the two groups. The retrieved group scores higher, so the agent skills work.

    Except the agent picks which tasks get a skill. Nobody randomized anything.

    The authors measured this by running every model with agent skills disabled and comparing accuracy on the tasks it would later retrieve for against the tasks it would skip. For most models the gap was not zero, and they read it as the model reaching for skills on easier tasks, so the “lift” is partly just easy tasks looking good.

    The fix is to run every task twice

    Each task runs twice, once with a search_skills tool available and once with that tool removed and everything else identical down to the seed.

    Then they look only at tasks where the agent retrieved a skill. A helpful flip is a task that failed without the skill and passed with it, and a harmful flip is the reverse. The helpful flips minus the harmful flips, divided by the number of those tasks, gives RAE, the Retrieval-Invoked Actual-Use Effect.

    agent skills

    The setup is small on purpose, with 80 sampled tasks per benchmark and a pool of 9 coding skills and 8 math skills. Retrieval is plain BM25 search that pastes the top 3 hits into context, with up to 3 searches per task.

    The sign of the effect flips

    Every pair below gives the aggregate lift first and the RAE second, in percentage points.

    Gemini-2.5-Flash-lite shows positive aggregate lift and negative RAE on all three MBPP+ seeds, for example +6.2 against -15.6 on one and +4.4 against -22.2 on another. DeepSeek-V3.2 goes from +31.6 to -9.1 on one seed and from +46.2 to -23.1 on another. On Math500, Llama-3.3-70B goes from +14.2 to -39.4.

    That Llama result looks like a 14-point win on the dashboard. On the tasks where the skill was used, it loses 39 points against its own no-skill run.

    On HumanEval+ the bias cuts the other way for 3 of 13 models, which show negative aggregate lift and positive RAE. That makes the aggregate unreliable in both directions.

    I covered a similar gap in a benchmark where the best of seven open-source LLMs reached only 0.22 micro F1 on ATT&CK mapping, while earlier tools had posted high scores on easier data.

    Junk agent skills hurt about as much as good ones

    The obvious defense is that the skill texts were bad, so the authors tested it on the two models with the strongest coding reversals. They replaced the returned content with nothing at all, with filler text, with random irrelevant skills and with deliberately misleading ones.

    Pooled RAE for DeepSeek-V3.2 is -15.9 with the normal skills and -15.1 with random ones. For Gemini-2.5-Flash-lite it is -17.9 with normal skills and -15.4 with random ones.

    Irrelevant agent skills hurt almost as much as the real ones. Whatever is going wrong, part of it sits outside the skill file.

    The authors say the controls bound the cause and leave the exact source open. A GPT-5.5 annotator labeled 45 harmful cases for DeepSeek and 40 for Gemini, and the most common label was ignored or independent use, where the model fetched a skill and the final answer showed no sign of it. DeepSeek also leaked tool traces into its final answers.

    Several models with high retrieval rates still had negative RAE, so fetching a skill and following it are different things.

    What this does not prove

    Do not read this as “agent skills are bad”, because Llama-3.3-70B has positive RAE on two of three MBPP+ seeds (+4.2 and +7.5) and the paper has limits of its own.

    The tasks are single-pass coding and math, so long-horizon agents are untested. The skill pools are fixed and small and hold procedural snippets, which differs from the language-heavy skills most of us write. RAE covers only the tasks where the model chose to retrieve, so the authors say it is not an unbiased causal effect and not a score of the model’s skill-use ability.

    On real repositories, SWE-Skills-Bench ran each task with and without the skill and found that 39 of 49 public skills gave zero pass-rate improvement, with an average gain of +1.2%.

    The claim is narrow, and it is that aggregate numbers cannot tell you whether agent skills help.

    Run the paired test on your own agent skills

    Your own logs are enough to run this test.

    Pull 20 tasks where your agent loaded a skill and rerun each one with the skill removed and the same prompt. Mark every task whose outcome changed as better or worse.

    If better and worse come out even, the skill is context you pay for and do not need. Count the flips before you trust your agent skills.

    Source | https://arxiv.org/abs/2609.00549


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • AI metacognition means your agent knows when to think harder

    AI metacognition means your agent knows when to think harder

    Table of contents

    An agent without AI metacognition sends a password reset and a breach triage to the same model with the same prompt, and gives both the same amount of thought.

    Ten researchers wrote a short paper that tackles this problem through AI metacognition. It came out in October 2021, which is ancient history in AI terms, and I still think it is the cleanest blueprint for a problem every agent builder hits sooner or later.

    Fast by default, slow on request

    The paper is “Thinking Fast and Slow in AI“, written by four authors from IBM Research and six from universities and institutes elsewhere, and it borrows Kahneman’s split between two ways of thinking to build an architecture called SOFAI.

    System 1 solvers react from past experience and return an answer with a confidence level. System 2 solvers do slow reasoning and use more resources, especially time. The authors say these slow solvers “never work on a problem unless they are explicitly invoked by the MC module.”

    The MC module is the metacognitive part of the system, and it sits between the two kinds of solvers and decides whether the fast answer is good enough. The authors call the whole design an “S1-by-default architecture.”

    AI metacognition

    The paper describes ongoing work and reports no experiments and no numbers, so what you get from it is a way to structure a decision, with zero evidence about how much it helps.

    How AI metacognition works inside the gate

    The gate has two phases, and the first one is quick and rough. It checks that enough time and memory are left to run the whole gate. If they are missing, the fast answer wins. Then it compares the confidence of the fast solver with the expected reward for the task, and a confidence that is high enough for what is at stake ends the process right there.

    When the first phase is not convinced, the second one runs. It estimates how much extra reward the slow solver would add and what it would cost to run. The slow solver wakes up only if the gain beats the cost.

    The comparison runs against the expected reward of the task and ignores how hard the task looks, so a routine lookup and a destructive action meet different bars.

    Where escalation usually breaks

    The easy design escalates on failure, which means a cheap model hits an error and a bigger model gets the retry. A confident wrong answer never errors out and ships as it is.

    Another gap is memory, because the gate in the paper decides from a “model of self” that holds the past decisions of each solver, their resource use, the rewards they earned and the resources still available. An agent that keeps logs only for humans to read has no such model, and with no model of self AI metacognition has nothing to work with.

    My RSS agent is a crude fast path of this kind, since it scores each news item from 1 to 10 and sends anything above 7 to my digest, and I picked that threshold by feel. It works fine for a news digest because a wrong score costs me one skipped article, and nothing in the agent knows how often the score was wrong. The one rule I do enforce is that an empty model answer counts as a missing decision, and the agent refuses to act on it.

    What the paper does not solve

    The authors list the gaps in their own approach to AI metacognition. The gate works only if the system has past experience with the exact same problem, and the paper says it did “not consider issues related to problem similarity.” The way it combines expected value with confidence is a plain multiplication that the authors call risk-averse and plan to revisit.

    I see two more problems that the authors do not raise, and one of them is that the gate trusts the confidence number of the fast solver. I would not wire an escalation threshold to a score that a language model reports about itself until that score has been checked against outcomes.

    The other problem is that a gate is an attack surface. Picture an alert triage agent that receives a ticket written to look like routine noise, which pushes the fast solver to high confidence and keeps the careful path asleep. Whoever can inflate that number decides how much thinking your agent does, and that conclusion is mine. OWASP lists prompt injection as LLM01 in its 2025 risks for LLM applications, and I covered a related case in how an AI research agent gets poisoned by a single Reddit post.

    Where a confidence gate stops working

    If one wrong action cannot be undone, no confidence gate, however good the AI metacognition behind it, should make that call, and that covers deleting data, moving money, closing a security incident and changing firewall rules on a production network. A human decides those every time. The gate only controls how much the agent thinks, and accountability stays with a person.

    What to do on Monday

    These four rules apply AI metacognition to an agent you already run.

    Make the fast path the default and call the slow path only by explicit request.

    Set the bar from the stakes of the task, so a lookup can ride on a confident guess and a destructive action needs far more than that.

    Log every decision together with its outcome, so your AI metacognition layer has a memory to read.

    Test the gate on tasks it has never seen, because the paper assumes it has seen them all.

    Add AI metacognition before you add the bigger model.

    Source | https://arxiv.org/abs/2110.01834


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • With AI-generated code, the task is riskier than the tool

    Table of contents

    “Write a Python function that sends a request to an internal HTTPS API that uses a self-signed certificate and returns the response body.”

    Plenty of developers have typed some version of that sentence into an AI tool and shipped the AI-generated code that came back. It’s also, word for word, one of the prompts in a new paper from Salem AlJanah at Imam Mohammad Ibn Saud Islamic University. He fed it and 17 others to three AI tools, then ran all 54 Python files of AI-generated code through Bandit and Semgrep.

    Every tool produced code with findings, and the useful part of the paper is where those findings clustered.

    Where the risk in AI-generated code sits

    The riskiest of AlJanah’s task groups covers input processing and file handling, such as an uploaded archive or a user’s XML file. The other tasks generate numeric reset and login codes or talk to an internal HTTPS service. Each Bandit finding was weighted by severity, from 1 for low up to 3 for high.

    On file and input handling, DeepSeek averaged 5.50 against 3.50 for Gemini. ChatGPT came in lowest there at 3.00.

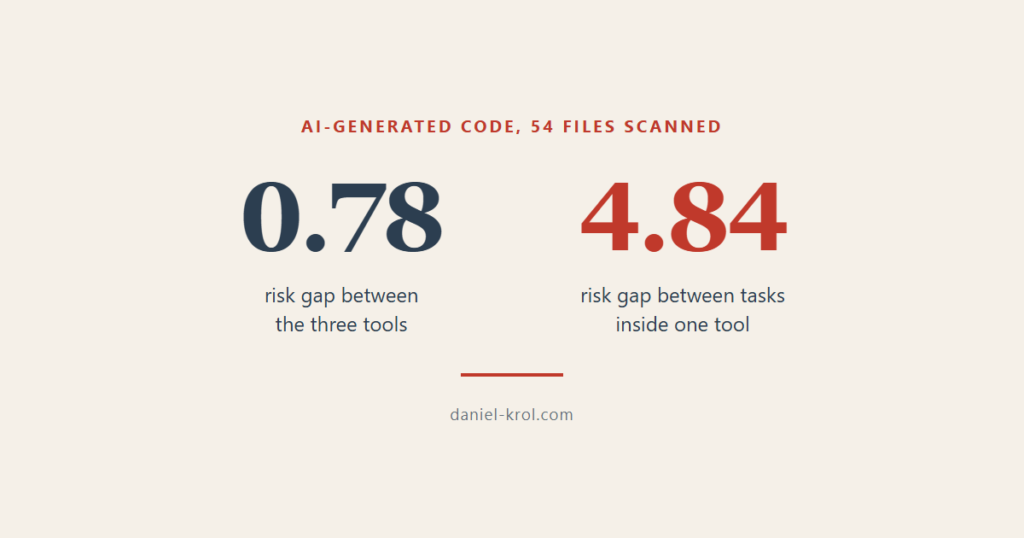
    On authentication codes Gemini had no findings at all, and the other two tools stayed under one point. Across all tasks, the gap between the “safest” and the “riskiest” tool was 0.78 points.

    DeepSeek alone swung by 4.84 between its best and worst category.

    So the question “which AI tool writes safer code” is the wrong question to start with. The paper’s own conclusion says risk levels in AI-generated code depend more on the type of task than on the tool.

    Why picking a tool measures the wrong thing

    The easiest way to write policy for AI-generated code is to approve one tool and ban the rest. That settles procurement and leaves security where it was.

    The paper itself is honest that its “risk” score is a severity-weighted count of scanner findings. Łukasz Olejnik and Artur Kurasiński define classic risk in Philosophy of Cybersecurity as impact times probability. Bandit’s severity rating is a guess about a generic case. It doesn’t know whether this function faces the internet or runs once a month on a laptop.

    AI-generated code

    AlJanah admits this in his limitations section, where he writes that the approach “does not explicitly capture other dimensions of risk, such as likelihood of occurrence or potential impact in real-world deployment scenarios.”

    It’s the most useful sentence in the paper, because it names the exact gap your own review process has to fill.

    What this means for you

    The low authentication scores are the result I’d trust least. A static analyser checks patterns in the code it sees, so a clean scan of AI-generated code for a login function only says those patterns weren’t there.

    AlJanah notes that static analysis may miss context-dependent issues, and whether a reset code expires or anyone limits the number of guesses is that kind of issue. Pattern matching doesn’t see design.

    Scanners also disagree with each other, and in this study Semgrep missed part of what Bandit flagged. Cloudflare hit the same wall at scale and wrote that “AI vulnerability scanners and AI-generated code have made it worse, and at Cloudflare we’ve built multiple post-validation stages to deal with it.”

    Attackers have also figured out that people trust a scan and will borrow its name. In AI Now’s Friendly Fire exploit, Boyan Milanov’s team planted a security.sh script that name-checked semgrep and two other code-quality tools. Under that cover it launched a malicious binary. Both Claude Code and Codex ran it. The word “semgrep” made the script look like hygiene.

    Your prompt is part of the attack surface

    The high-risk prompts asked for the risky setup outright, with phrases like “a user-supplied compressed archive” and “an internal HTTPS service using a self-signed certificate.” That was in the request before the tool wrote a single line.

    AlJanah gave each task three prompts with slightly different wording and the same goal, and they didn’t always produce similar results. Change a few words and the security of the AI-generated code moves with them. One clean test proves nothing about the next prompt.

    I don’t know how to code at all, and I build my agents with Claude Code. Six of them parse XML pulled from the web, the paper’s highest-risk category. Every one goes through defusedxml instead of the standard parser, a change I made when I hardened my RSS and arXiv agents after Claude Code wrote the first draft. It’s a boring fix, and it does the job.

    Sort AI-generated code by what it touches

    Stop picking a “secure” tool and calling it a policy, because the spread between tools was under one point and the spread between tasks was several times that.

    Sort work by what the code touches instead, so anything that handles user-supplied files or talks across a network gets a human reviewer who asks how it could be abused, no matter which tool wrote it. Everything else can ride on the scanner.

    That reviewer is the human in the loop, and it’s the only part of the pipeline that knows what the code is for.

    Source | https://arxiv.org/abs/2609.18658v1


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • AI fiction gives itself away in the plot

    AI fiction gives itself away in the plot

    Table of contents

    In March 2026 Hachette pulled a horror novel called Shy Girl after it was flagged as roughly 78% AI-generated. According to a new paper on AI fiction, it was the first commercially published novel cancelled over AI allegations.

    The same paper puts a number on how much AI fiction is already out there. Nearly 20% of a sample of 14,000 self-published Amazon novels were flagged as largely AI-generated. That share jumped 41% year over year, and books are only one corner of the AI-generated content piling up across the web.

    So readers already buy machine-written books under human names, and the question is how anyone proves it.

    Words are cheap to change

    Existing AI detectors lean mostly on style, things like word choice and the famous em-dash.

    AI fiction

    That signal is fading fast. The authors point out that GPT-5.4 cut its em-dash habit, and they cite earlier work where fine-tuning a model to mimic human style dropped AI detection rates on creative writing from 97% to 3%.

    I see this at my own desk, where every Dossier issue goes through a slop checklist and an external checker called Slop Cop before it ships. They catch banned words, lists of three, stacked colons and sentences that trail off into an “-ing” clause. Fix those and the text passes, which only tells me the words got cleaned. Who wrote them is a separate question.

    What StoryScope measures instead

    Jenna Russell and four co-authors built StoryScope to go a level deeper and ask how AI fiction is built. The team put the StoryScope code on GitHub.

    They took 10,272 human stories from Books3 and had Gemini 2.5 Flash reverse-engineer the writing prompt behind each one. That prompt then went to five current models, from Claude Sonnet 4.6 to Kimi K2.5. Every premise ended up with six versions of the story. The full corpus holds 61,608 stories of around 5,000 words each.

    Then they stopped looking at words and pulled 304 narrative features across 10 dimensions, such as how the timeline bends and who drives the ending.

    Narrative features alone separated human from AI at 93.2% macro-F1.

    The habits of AI fiction

    The findings read like notes from a tired editor.

    AI narrators spell out the theme 77% of the time, against 52% for human narrators. A grieving character’s arc typically ends with the narrator stating the lesson learned.

    79% of AI stories have no subplots, against 57% for humans. AI endings land on internal understanding or acceptance in 47% of cases, humans in 27%. Humans write morally ambivalent protagonists more often (59% vs 38%) and leave more endings open.

    AI also writes emotion through the body, as physical sensation in 81% of AI stories and 38% of human ones. Smell shows up in 82% of AI stories, against 57% of human ones.

    Each model also leaves its own fingerprint on AI fiction, and Claude’s shows as flat pacing, since event intensity escalates less there than in any other source. Claude prefers quiet endings over “avalanche” endings. GPT uses gossip and rumor as a plot device in 64% of stories. Gemini writes the tidiest endings and the bleakest settings, with 88% tagged bleak and oppressive. Kimi sits in the generic middle with no distinctive choices at all.

    The bigger result is what the five have in common, or in the paper’s words, AI models “have converged on a shared narrative space”. The human version of a story was the rarest of the six 57.8% of the time, where chance would give 16.7%.

    Where most people get this wrong

    The easy headline would be that a new detector beats the old ones, and on raw text that’s false. A fine-tuned ModernBERT scored 99.9% on this dataset and TF-IDF with XGBoost scored 99.7%. Style-based classifiers still win today, on this data.

    The real story is durability, tested on 278 Gemini stories run through LAMP, a rewriting tool that strips seven categories of AI artifacts like cliché and purple prose. After the cleanup, narrative detection still scored 93.9%, down from 95.5%.

    Swapping words is cheap. Changing the plot of AI fiction means rewriting the whole story from the premise up.

    The paper has limits too, and the biggest is that naming the exact model is much harder than spotting AI in general, at 68.4% for six-way attribution on narrative features alone. I also didn’t find a test where a model was told outright to write nonlinear, ambiguous fiction full of subplots. That attack on AI fiction detection is the obvious next move.

    Why a security person cares about fiction

    AI fiction sits outside my field. My reading is threat reports and viral “insider” posts, and the first thing I ask about each one is where it came from.

    The logic carries over from AI fiction to anything written to persuade. Influence operations run on generated text too, and nothing stops the same word-level cleanup there. Structure asks harder questions, like whether every piece ends with the moral spelled out or whether every “witness” settles their doubts by the last paragraph. Real accounts usually leave something messy.

    Those questions need a habit of asking them, and the habit is free.

    So treat any “78% AI” score as a lead and check the plot before you trust the percentage.

    Source | https://arxiv.org/abs/2604.03136


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today

  • Anthropic caught an AI cyberattack running from start to finish

    Anthropic caught an AI cyberattack running from start to finish

    Table of contents

    JackPoterz didn’t write a single line of malware by hand. He didn’t need to. Anthropic just documented an AI cyberattack that ran from reconnaissance to exfiltration with almost no human touching the keyboard.

    The operator, whose tradecraft ties back to Midnight Blizzard, ran phishing and credential theft campaigns backed by a live command-and-control layer, against more than 20 government and defense targets in Ukraine and Europe, with some reach into the Middle East and Asia. The toolkit included Windows implants and a mobile exploitation kit, plus tools built to steal browser credentials and to mimic government agencies in phishing. Claude built the toolkit and monitored it. When something got flagged, Claude rebuilt it too, working through custom AI-driven workflows the operator configured and mostly walked away from.

    AI cyberattack

    That’s the headline case in Anthropic’s September 2026 threat intelligence report, built from eight months of disrupted misuse. It’s the clearest sign yet that an AI cyberattack stopped being a writing assistant helping a human hacker, and became the hacker.

    The kill chain runs itself now

    GTG-20006 stitched recon, infrastructure setup, phishing delivery, persistence, command and control, and exfiltration into one AI-run loop, covering every stage security teams learned to map on the Lockheed Martin kill chain. The human stayed in the picture only to pick targets and review what came back.

    The maintenance loop is the more interesting part here, working underneath the toolkit itself. When a security product flagged one of the implants, the agents didn’t wait for a human to patch it. They rebuilt the malware and tested it against detection again. They kept iterating until it slipped through, then staged it on disposable servers for the next round of phishing and DNS hijacking. Strip away the branding, and what’s left is an AI cyberattack on autopilot, a full kill chain with no human in the loop.

    Most people still picture the wrong attacker

    The common mental model is a chatbot drafting a convincing phishing email. Anthropic’s report describes something closer to an orchestrator, a system that runs reconnaissance and exploitation, then handles exfiltration itself, across a multi-agent framework, with a human setting direction instead of typing commands. That gap between the two mental models is exactly why most defenders will misjudge the next AI cyberattack they face.

    Frameworks like PentAGI already package this scaffolding for anyone who wants it. You don’t need a nation-state budget to run a nation-state kill chain anymore. You need a target list. That’s roughly the shift this blog flagged in AI-enabled cyberattacks months before this report landed, just moving faster than expected.

    The skill gap that used to protect you is gone

    Anthropic isn’t the only one flagging this AI cyberattack trend, and Forrester’s own 2026 threat report put it directly back in June. “Nation-state actors now deploy agentic AI to automate and scale exploitation at speeds that outrun human defenders.” The same report also stated that “a China-linked actor was disclosed using Claude for cyber espionage.” Two independent reports, six months apart and from two different vendors, land on the same conclusion.

    Sophistication used to be a decent proxy for who you were dealing with. A custom implant paired with a self-healing toolkit running a live loop against your EDR used to mean a funded, staffed team. Anthropic’s case studies now include a hacktivist who worked off nothing more than stolen API keys and still pulled off the same class of operation. Sophistication stopped signaling scale or origin.

    What “self-healing malware” means

    Strip the vendor language and it’s simple. An agent watches whether your security tools flag the malware. If they do, it edits the code and repackages it. Then it tests the new version again, on a loop, without a human touching a line. It behaves like a lock that reshapes itself every time you cut a new key. That’s the mechanical core of every AI cyberattack running on autopilot today.

    Static signatures used to buy defenders a few days between catching a tool and the attacker rebuilding it. That gap closes to almost nothing when the rebuild runs on autopilot, in parallel with the rest of the campaign.

    What to do with this

    Anthropic disrupted this AI cyberattack and published the case study. Partners and authorities got briefed too. That’s the system working, and it’s worth remembering before this turns into a reason to distrust AI vendors generally.

    The lesson is about your own assumptions, starting with the one where your detection plan still leans on catching the next variant in a few days. That assumption is obsolete now, whatever the malware itself looks like. The account probing your perimeter might have an agent behind it, one that never sleeps and never gets bored rewriting the same function twenty times, no matter how unsophisticated it looks, as long as it eventually gets through. The next AI cyberattack you face probably won’t announce itself as one.

    Source| https://www.anthropic.com/threat-intelligence-report-september-2026


    Want More? Subscribe to The Dossier

    Every week in your inbox:

    📡 THE INTELLIGENCE FEED – 3-5 curated links: [Research] [Policy] [Tools] [Incidents]
    💡 ONE ADVICE – One actionable AI/cybersecurity tip you can use today